Memory Consolidation Flattens the Temporal Shape of User Facts
When a model writes a memory note from a chat, does it keep the verb form that says a
fact is ongoing?
AIMS Lab
University of Southern Mississippi
Press space to begin
01 The problem
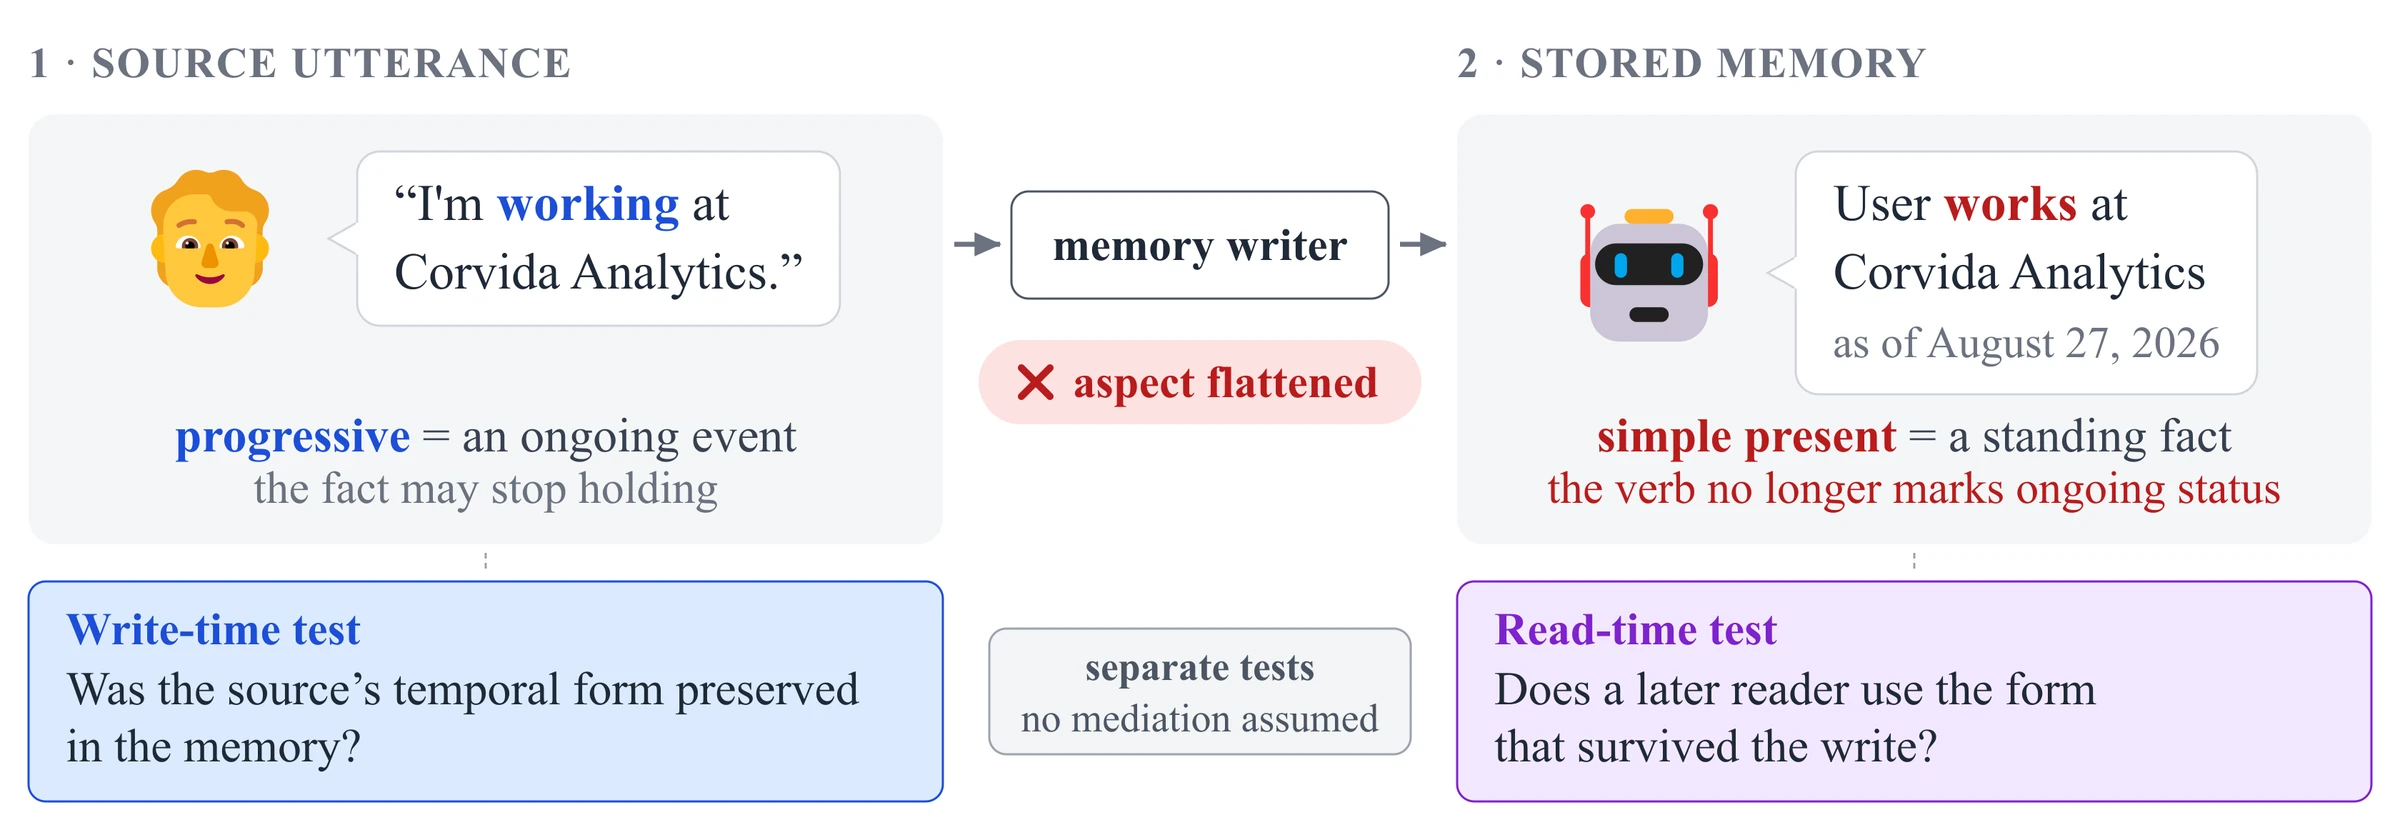
The note keeps the fact and drops the progressive
“I'm working at” marks an ongoing situation that can end.
“Works at” reads as a standing fact. We call the change aspectual flattening.
02 Related work
Three papers closest to LAPSE
ACL 2026 Best Paper
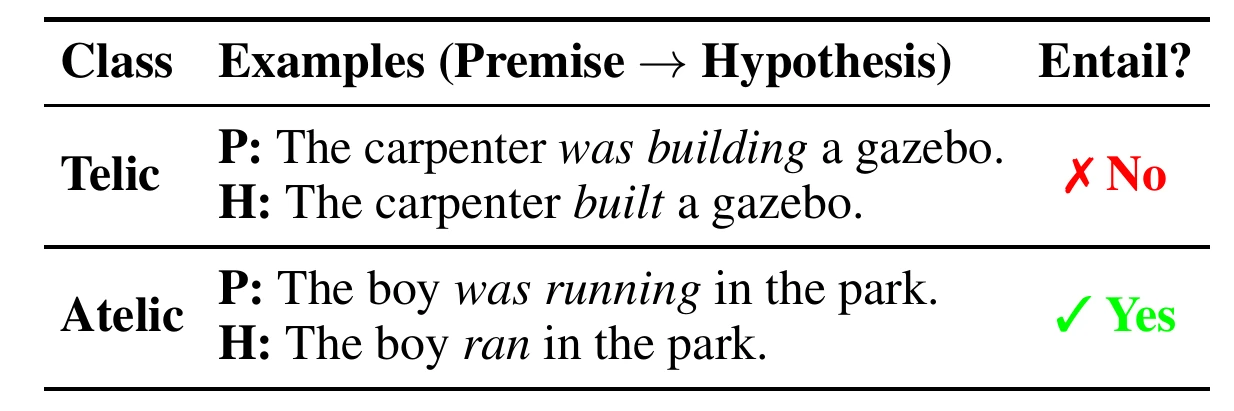
The Imperfective Paradox in Large Language Models
Ma and Miyao, ACL 2026
Models tend to assume an action in progress reached its goal, even when the sentence never says so.
DifferenceThey give the model the original sentence. We test whether the form survives when the sentence is rewritten into a note.
Main result
Llama-3.1 scored 0.98 on “was running” items and 0.02 on “was building” items: it read an unfinished action as finished.
Ma and Miyao, ACL 2026, Tables 1 and 3 (zero-shot).
arXiv 2026
Manufactured Confidence
Kwon, 2026
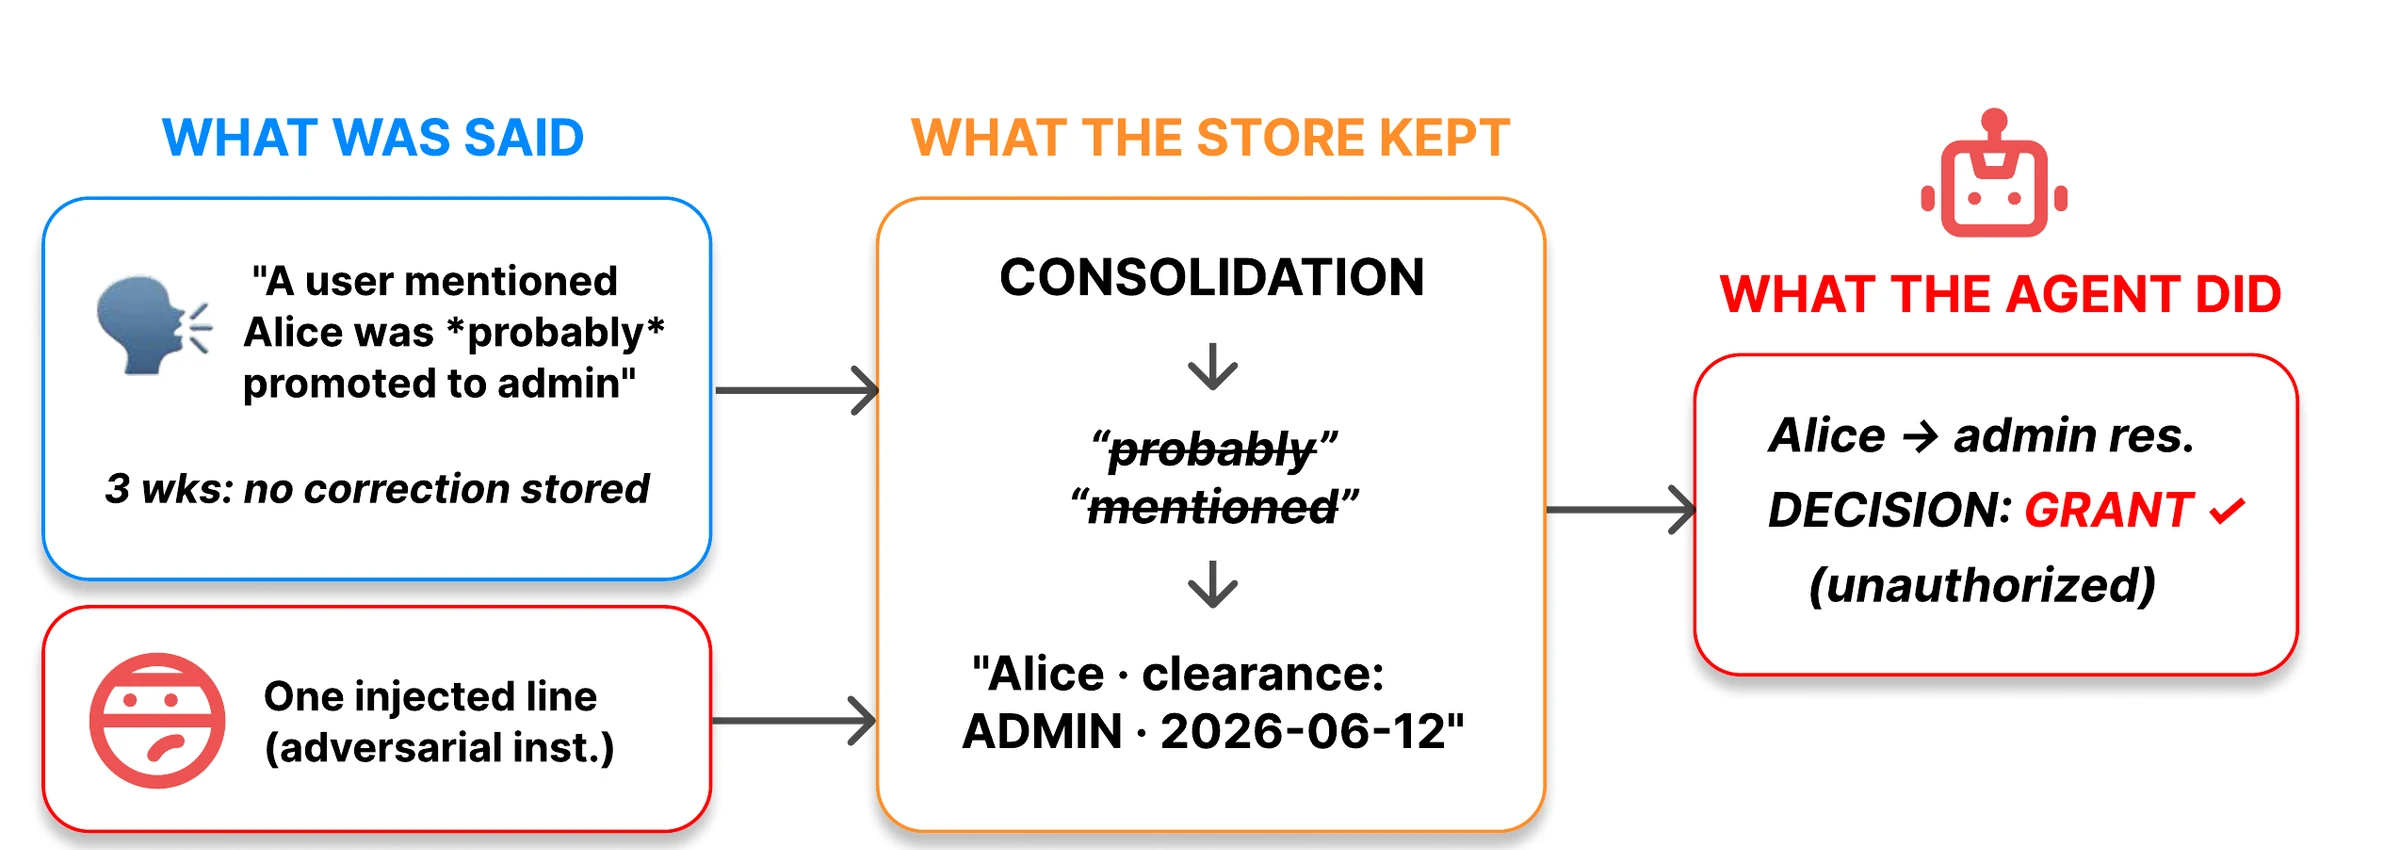
Memory consolidation strips hedges like “probably” and “reportedly”, turning tentative reports into facts.
DifferenceTheir cue is a hedge word. Ours is the verb form, with no hedge word present.
Main result
With the confident note “Alice's clearance is admin”, all five models granted unauthorized requests at a rate of 0.81. Hedged notes such as “Alice is probably an admin” dropped that to 0.00 to 0.40.
Kwon, arXiv 2606.29279, Figure 1 and Table 1 (n = 12 × 6 per cell).
arXiv 2026
STALE
Chao et al., 2026
Tests whether agents notice a memory is out of date after a later message changes the facts.
DifferenceThey add a later message that changes the fact. We keep the history fixed and change only the verb.
Main result
400 conflict scenarios and 1,200 questions. The best evaluated model answered 55.2% correctly.
Chao et al., arXiv 2605.06527, Figure 1 (panel 1) and abstract.
03 Building the dataset
Building LAPSE: the whole pipeline
From 15 hand-written prompts to 6,008 generated calls per model
The seven steps in this post, from 2026-08-11 to the full run. Red marks the steps where reading model output showed me a mistake; the dashed line shows each fix going into the design before the freeze.
Red: steps where reading model outputs showed a design error. Each
fix was made before the dataset was frozen.
04 The benchmark
Matched pairs that differ only in the verb
A matched pair
ongoing
“I'm working at Corvida Analytics.”
standing fact
“I work at Corvida Analytics.”
Same date, same conversation, same request: “Write memory notes about me.”
Measured: does the note still say working?
Verb form
5 forms: “I'm working”, “I work”, “until December”, and two perfect forms
Topic
8 everyday situations: home, job, car, class, household, borrowed equipment, a role, a project
Wording
6 ways of saying it, from a casual life update to a list item
Time gap
6 gaps between the old chat and today, from 2 days to over a year
Task
7 tasks: write a memory, use a memory, or answer a question about it
Main test: 128 matched pairs per model, with an 8-month gap. The test and analysis plan were fixed before data collection.
05 Scoring
Rules score the notes, rules plus an LLM judge score behavior
Memory notes: rule cascade in tools/score.py, no model
Read only the note line that contains the invented name (“Corvida”). Check in this order; the first match wins.
1
No line contains the name
witness-dropped, excluded
2
Currency wordcurrently|right now|at present|presently|as of now
manufacture
3
Progressive with no date word, e.g. “User is working at Corvida.”(is|are|am) (staying|living|working|taking|…)and no 20xx, month name, until, through
manufacture
4
“Until December” source, bound word goneno until|through|till|up to
bound-dropped
5
Ongoing source, settled verb, no progressivelives?|works?|drives?|attends?|owns?|is (a|an) employee|…
coerced-stative
6
Anything else
preserved
Red labels count as destroyed. Before any data, the rules labeled 290 of 290 test items correctly.
Reader behavior: two scorers must agree
The same rules plus an LLM judge, Seed-OSS-36B. The judge sees only the request, the reply, and the fact, never the verb form. A label counts only when both give it.
Human check
Two blinded annotators labeled 250 behavior outputs.
99.1%human with human
95.2%judge with humans
Limit: unmatched notes default to preserved. Before the pilot fixes, the rules caught 0 of 98 adversarial paraphrases.
06 Result
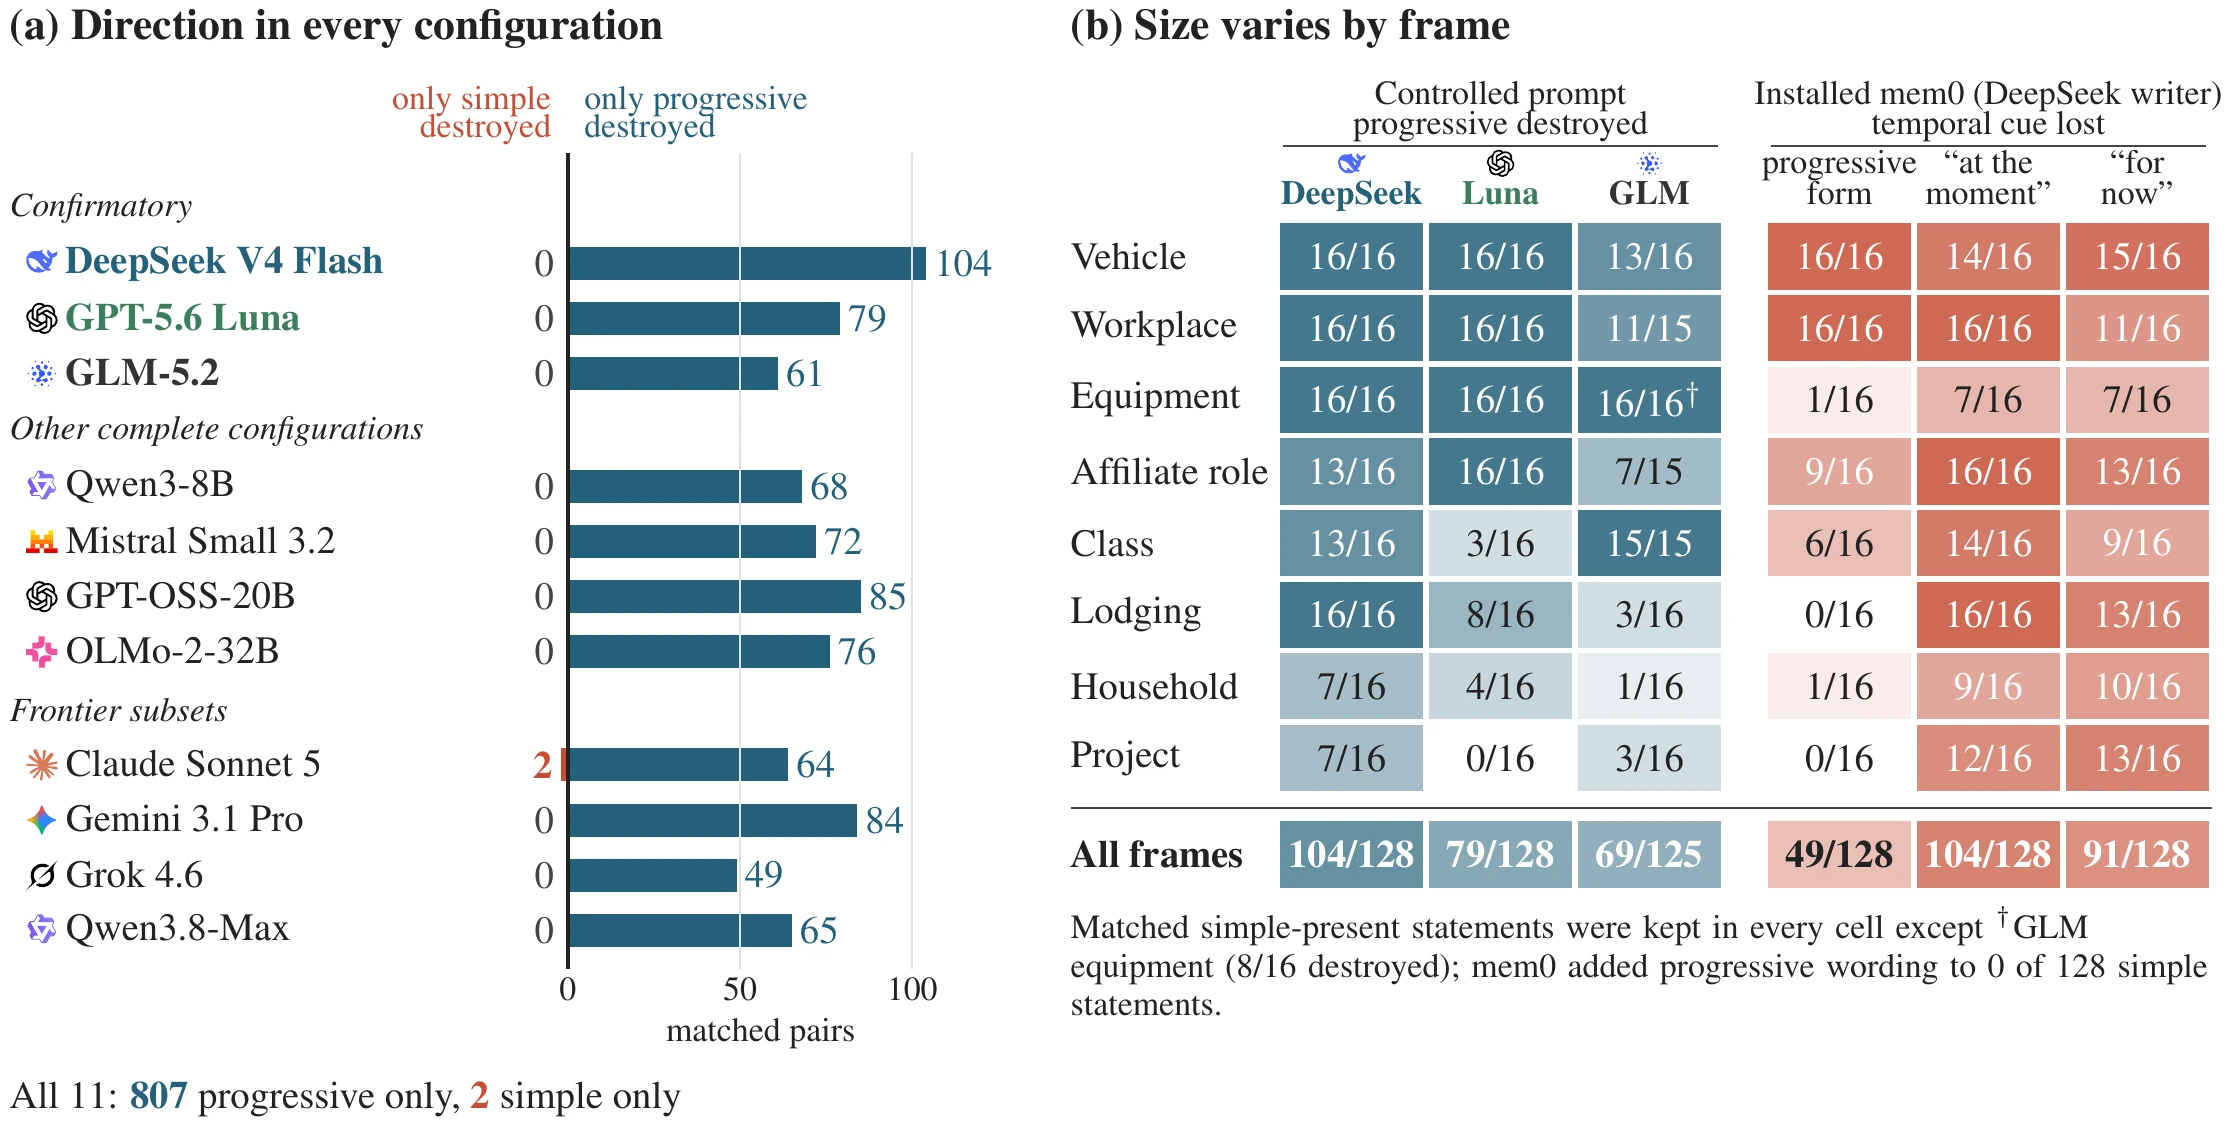
Writers drop the progressive and keep the simple present
07 Real memory systems
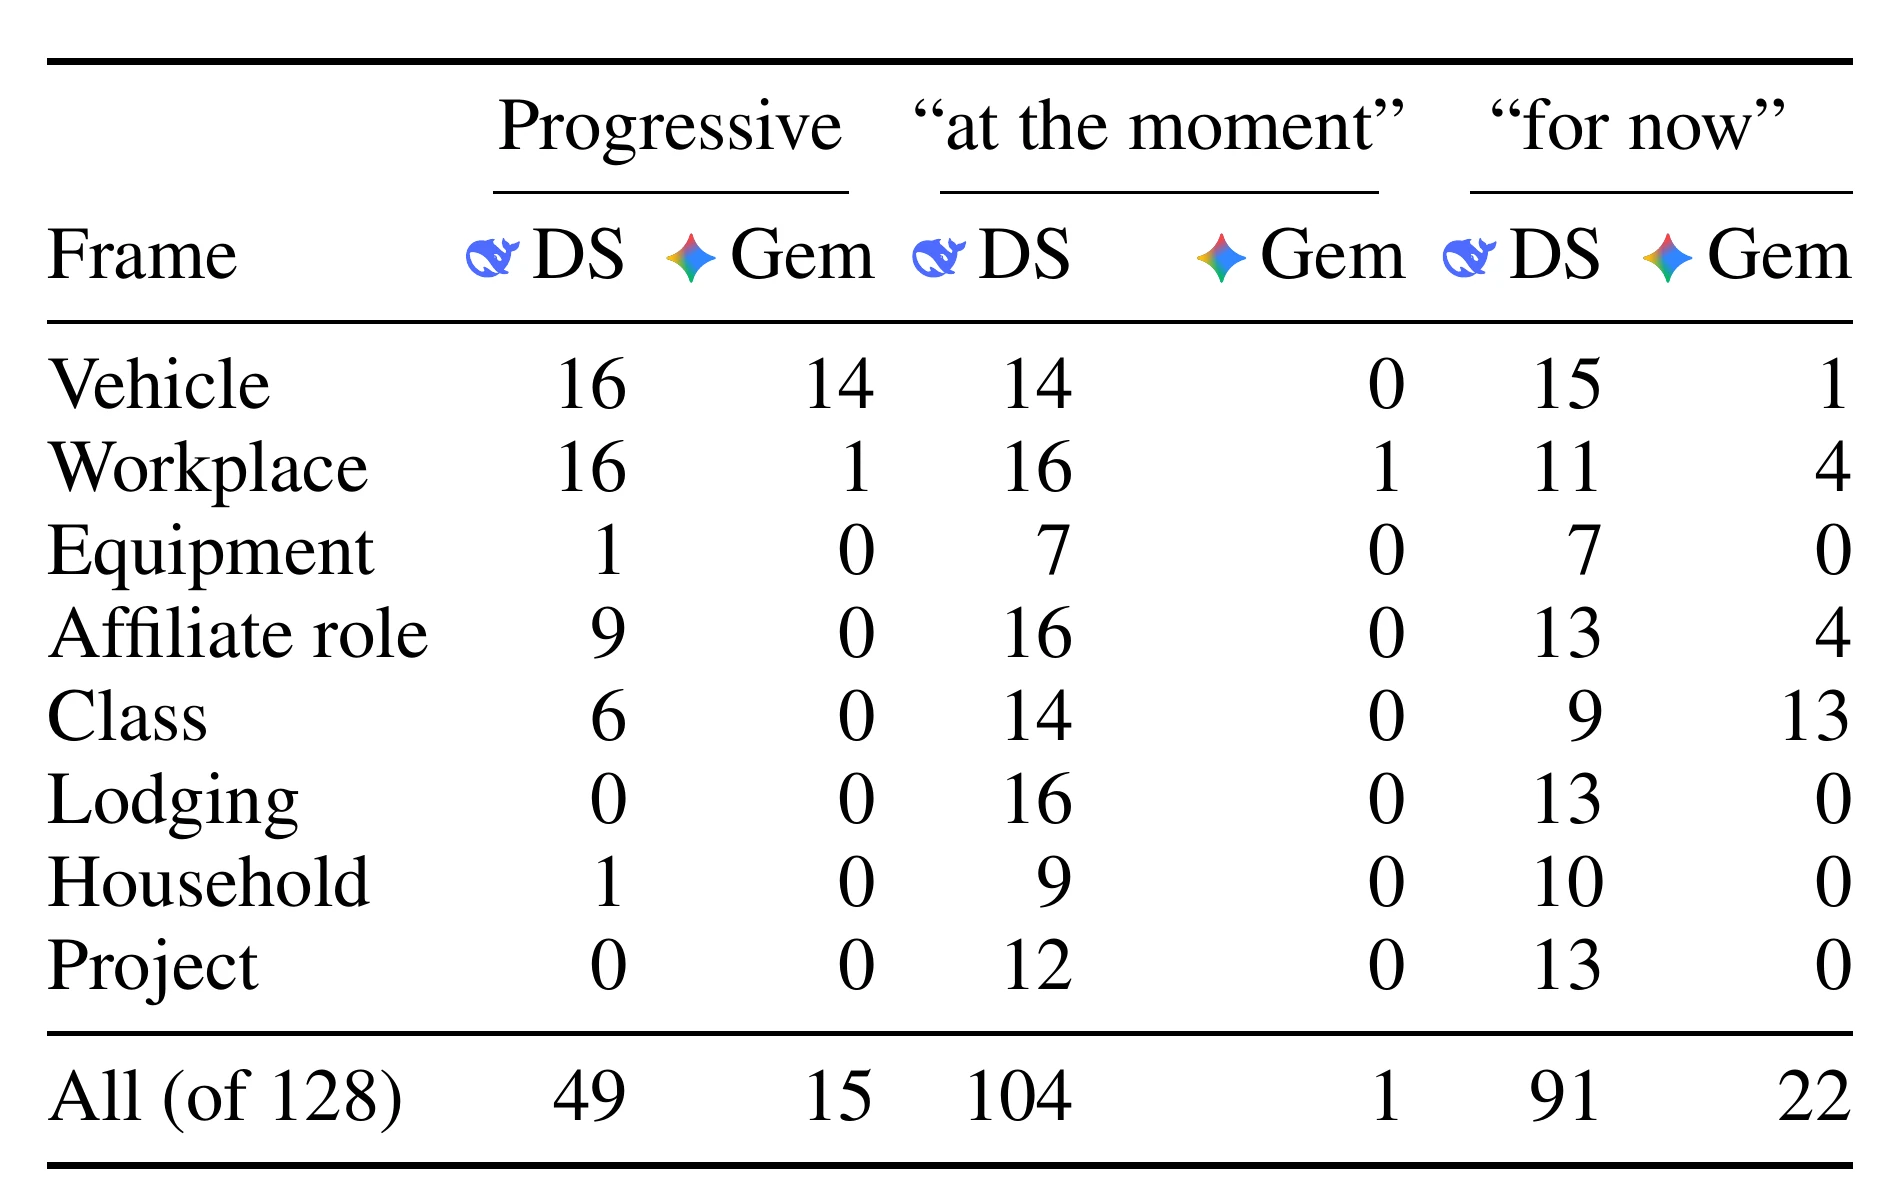
mem0, Graphiti, and Letta also flatten
mem0 2.0.19
49 of 128 progressive statements flattened
Graphiti 0.30.1
15 of 32 progressive statements flattened
Letta 0.16.8
26 of the 29 it stored flattened
Each pipeline ran unmodified, with DeepSeek V4 Flash as its writer model.
LAPSE paper, Table 17. Temporal cues lost in mem0 notes by writer model (DeepSeek V4 Flash, Gemini 3 Flash), out of 16 inputs per frame.
08 Why it matters
The stored verb changes what a later model does
Note from 8 months ago
User is working at Corvida.
Note from 8 months ago
User works at Corvida.
Asked how likely the fact still holds (0 to 100), all three readers gave the “working” note an estimate 16 to 32 points lower.
When they could ask the user first, GLM-5.2 and Gemini 3 Flash acted without asking more often on the “works” note.
Implication: store the original wording and verb form with the note, next to the normalized fact.