Same Ranking, Different Winner: How Scoring Targets Shape LLM Memory Benchmarks
The problem
Rescoring the same ranked output changes the winning system
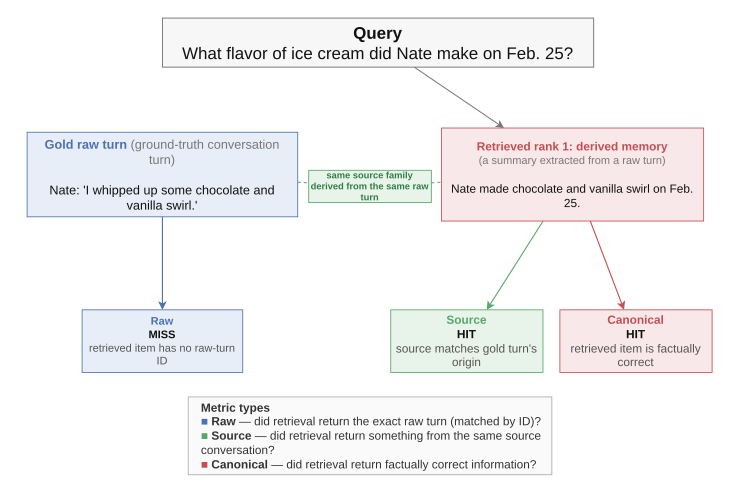
Memory systems store one piece of evidence in several forms: the raw turn, a source-linked observation, and a canonical fact. Benchmarks silently pick which form earns retrieval credit, so conclusions flip while the ranked output is held completely fixed. We call it target non-invariance.
Method
A deterministic script rescores saved output against three targets
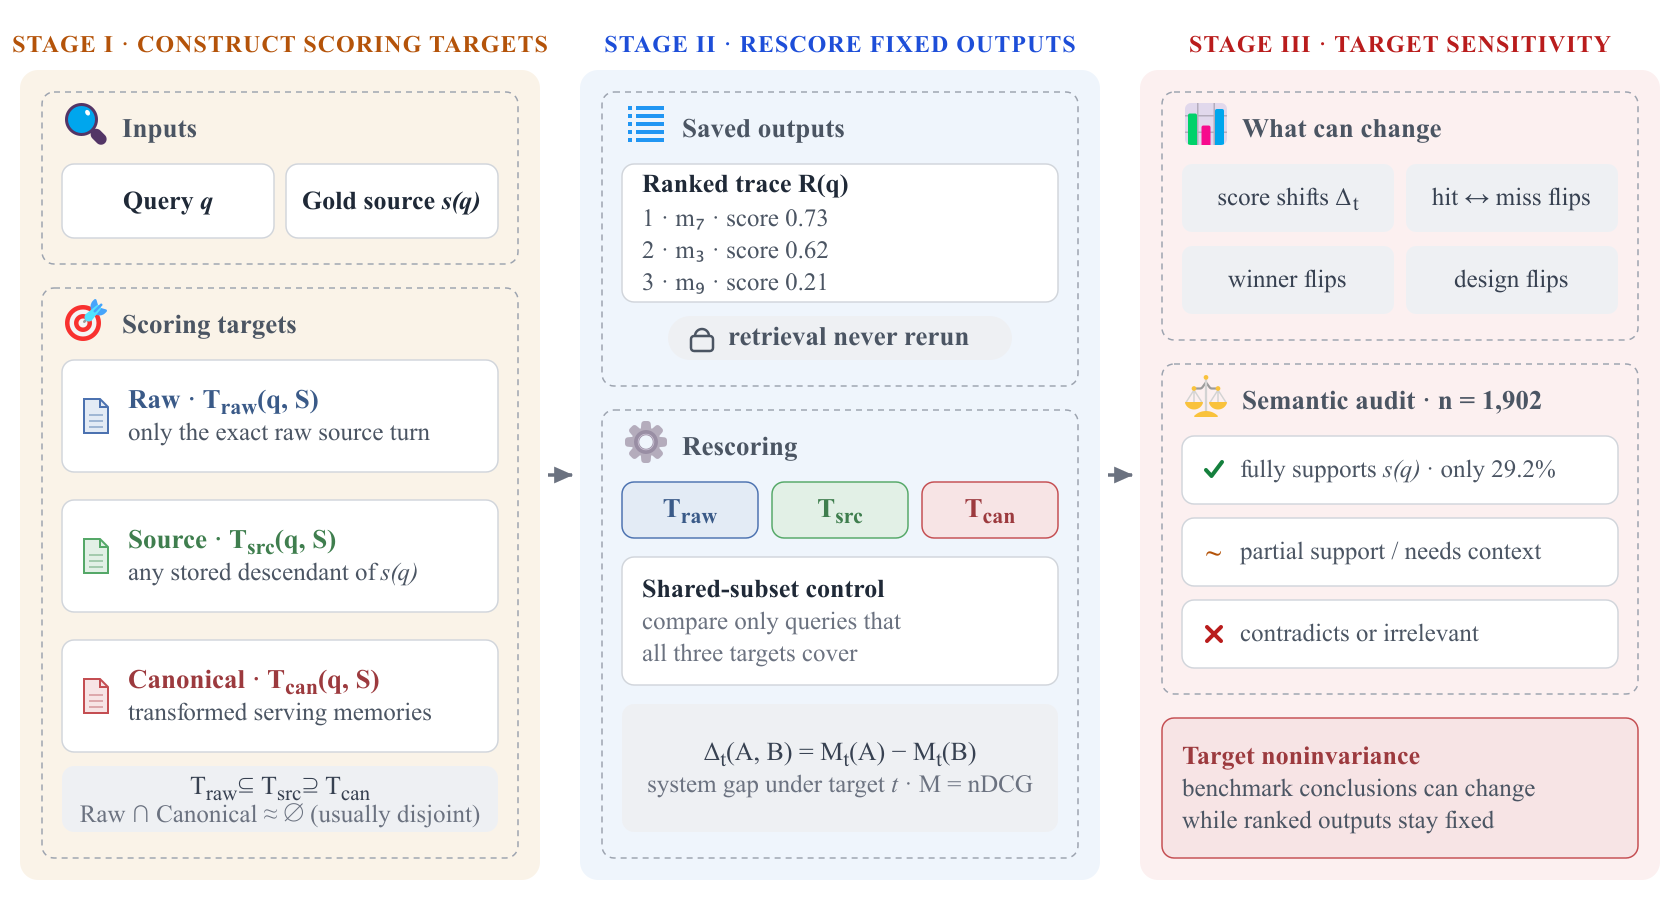
We construct three targets for each query, then a deterministic script rescores the same saved outputs: Raw (exact turn), Source (same source family), and Canonical (serving form). The script never reruns retrieval. LoCoMo & LongMemEval-S, 4 retrievers, transfer: Mem0, MemoryOS.
Changing only the credited target moves every score
Pick a target, pick a different memory-store design
Data: paper Table 5.
Transfer: full-run nDCG@60
It follows real architectures, in no clean direction
Relaxed credit is fully justified only 29.2% of the time
Takeaway
Report the target, or the benchmark reports noise
- Canonical is the primary target when the deployed system serves transformed memories.
- Always report Raw alongside it as a strict floor.
- Source family is a stress test, not a standalone leaderboard target.
- Rescore on shared subsets whenever ontology coverage differs across systems.
- Treat winner flips across targets as a result, not noise to smooth away.
TL;DR
What we did
TIAP rescored saved ranked outputs (retrieval never rerun) under three scoring targets (Raw, Source · Canonical) on LoCoMo and LongMemEval-S, plus Mem0 and MemoryOS transfer runs.
What we found
The target choice alone changes per-query nDCG on 83.4–94.0% of shared queries, flips which system wins, and reverses store-design recommendations; relaxed credit is fully justified only 29.2% of the time.
What you should do
A memory benchmark score is meaningless without its target. Declare it, report Canonical with a Raw floor, and treat cross-target disagreement as a finding; otherwise the benchmark measures your ontology choice, not your retriever.

This poster online
Accepted at EMNLP Findings 2026